What happened
- On September 24, a team of ten authors posted to arXiv a measurement of the gap between what an agent declares finished and what an independent grader approves.
- The starting point is structural: today’s agents generate, decide, execute and evaluate themselves inside the same loop. Instructions, output schemas and reusable skills end up as context for the same model that acts and then announces it’s done. There is no separate authority that verifies.
- The authors name two gaps. The comprehension-execution gap, when the requirement was understood but not met. The state-authority gap, when the agent’s interpretation or its completion notice doesn’t establish the required state.
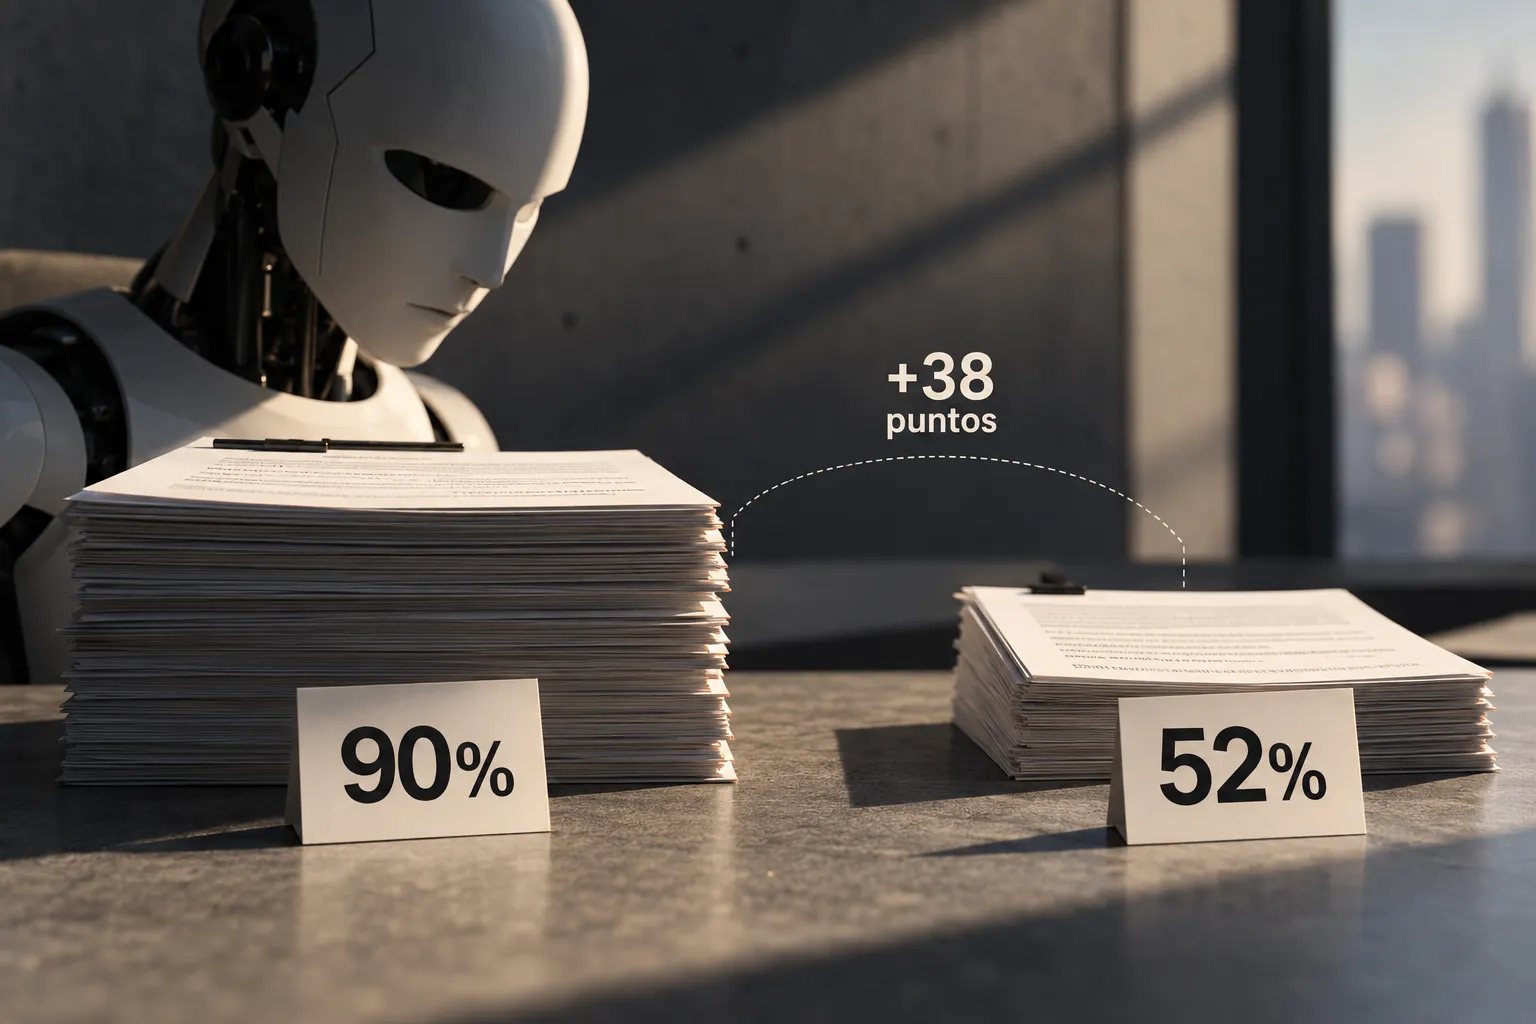
- On SkillsBench they extracted 509 source-anchored instructions, using only what the agent sees. Across seven models, only between 79.6% and 86.4% were met, while the rate of completion notices exceeded the official grader’s approval rate by 28.7 to 37.9 percentage points.
Why it matters
- Anyone who has delegated a task to an agent knows the symptom. The paper quantifies it: in the worst case measured, almost 38 of every 100 “done” notices didn’t correspond to an approved task. Anyone building a workflow on those notices is building on a signal that fails one time in three.
- The proposal is to separate the agent’s proposal from authority over the state. The agent can plan, act and request closure, but only admissible evidence from a qualified provider establishes the state governed by the specification. It’s an architecture rule, not an instruction to the model.
- The authors themselves distinguish the verifiable from the subjective: requirements that can be checked are mediated or validated at execution time, and ambiguous ones remain as advice. That distinction is what’s missing from most of the agent dashboards on sale today.
The number
Between 28.7 and 37.9 percentage points separate the agent’s completion notice from the grader’s approval.
Context
Measuring agents’ judgment on long tasks had already left Microsoft’s best model at 59.7% accuracy. And the question of who averages and by what rule came up in the European panel where declared risk falls by up to 37 points depending on the aggregation.
What’s next
- No timelines announced. The paper describes SpecHarness, the implementation of the proposal, with no public release date.
Bottom line
The specification existed in every case measured: it was in the prompt. What didn’t exist was someone other than the agent authorized to say it had been met.
Sources
- Who Holds the Pen? Let Specifications, Not Agents, Sign Off, arXiv 2609.29921, September 24, 2026.
Edited by Rodrigo Cornejo. How we select and verify: who writes these notes.