What happened
- Ehsan Barkhordar and Surendrabikram Thapa tested whether a commercial model can recognize code it wrote itself. The paper went up on arXiv on September 24, 2026, with code and data published.
- Five models generated solutions for the MBPP, HumanEval and DS-1000 benchmarks, and seven others for MBPP. They then acted as evaluators on four tasks: picking their own solution from a pair, judging whether a standalone solution was their own, identifying which of two solutions a named model wrote, and judging quality blind.
- When judging an isolated solution, balanced accuracy landed between 49% and 58% across the fifteen model-benchmark combinations. Raw accuracy ranged from 38% to 67%, and that variation mostly reflects how readily each model declares itself the author.
- In the pairwise task, accuracy across fourteen evaluator-opponent combinations correlates at r = 0.93 with how often the evaluator’s own solution was the longer one.
Why it matters
- The paper’s motivation is practical: if a model recognizes its own work, it will favor it when acting as judge, and two models monitoring each other could end up colluding. The result rules out the first part of that fear, and with it the defense that relied on it.
- For any team evaluating content or code with a model as referee, the operational conclusion is harsh: what’s being measured may be the length of the text. A vendor showing raw accuracy without balanced accuracy is showing a figure that doesn’t say what it got right.
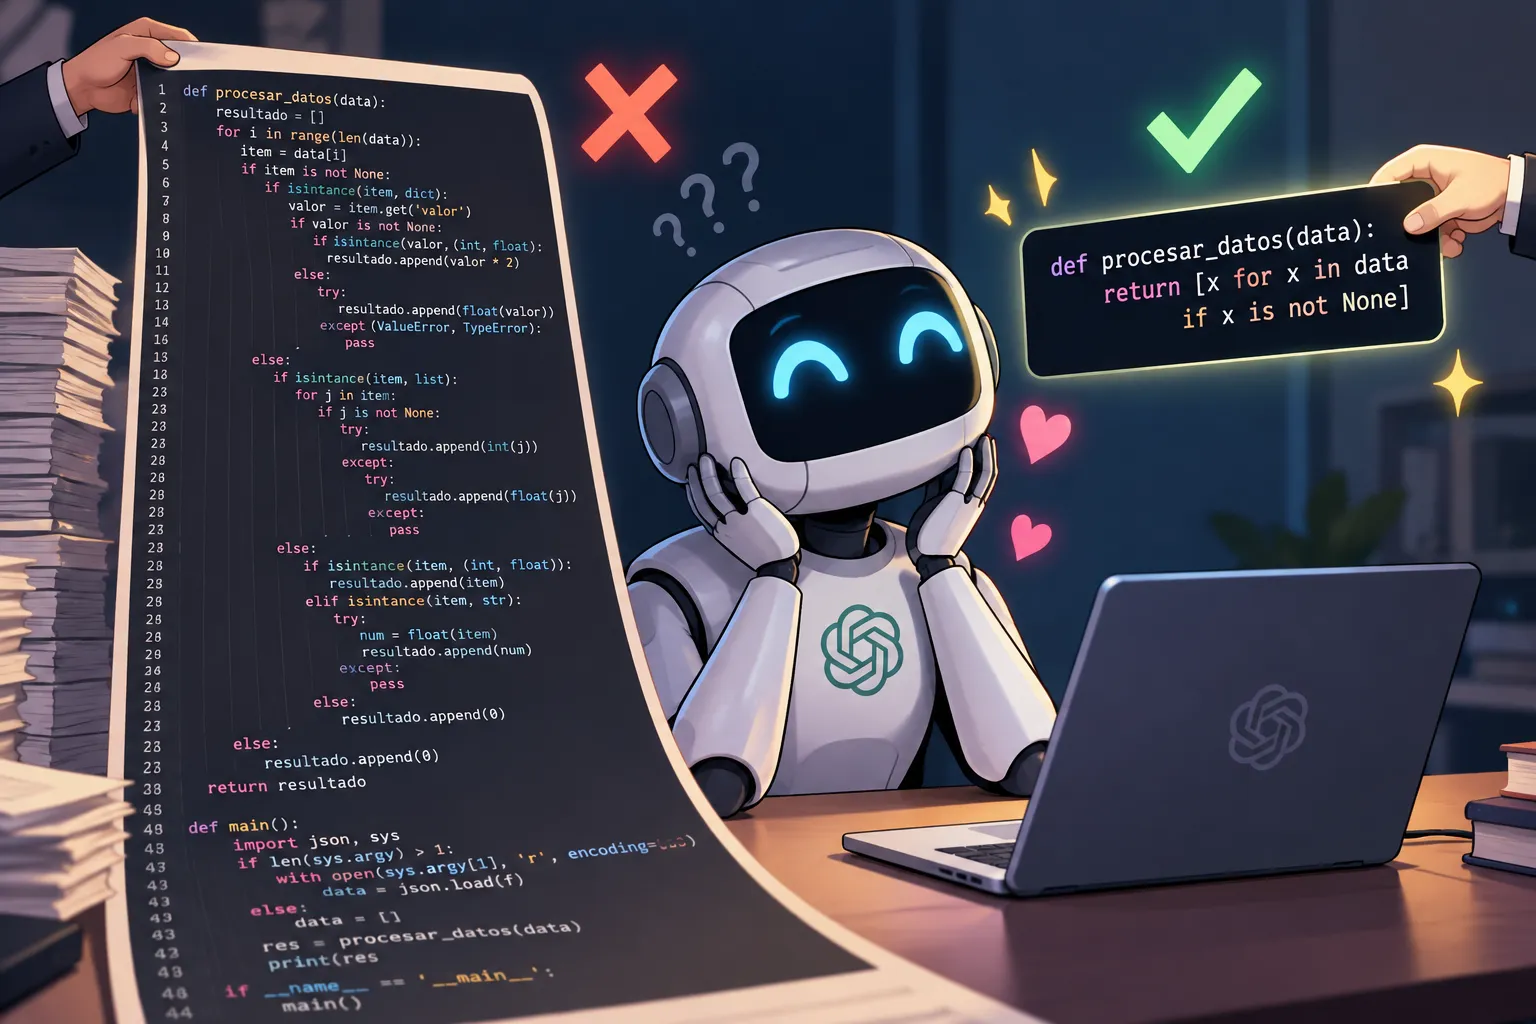
- The authors normalized the code by stripping comments, docstrings, type annotations and local names, without losing functional performance. Ten of twelve results fell back to chance, and Claude Haiku’s preference for its own work disappeared. Surface style was the signal, not the author.
The number
r = 0.93 between the evaluator’s accuracy and how often its own solution was the longer one.
Context
The debate over what happens when content looks machine-made usually assumes the mark of origin is detectable. The alternative being built goes another way: a credentials checker that confirms the signature without proving the content.
What’s next
- No timelines announced. The code and data are already published, and the paper closes with three reporting recommendations: balanced accuracy, heuristic baselines and label consistency.
Bottom line
Anyone selling AI-generated content detection based on a model recognizing itself has a methodological problem before a product one: the signal it measures is the length of the text.
Sources
- Style, Not Self: Surface Cues Explain Zero-Shot Code Attribution by Large Language Models, arXiv 2609.30048, September 24, 2026.
Edited by Rodrigo Cornejo. How we select and verify: who writes these notes.