What happened
- A team of more than 20 authors published FDE-Gym on arXiv on October 15, 2026, a benchmark of AI agents for end-to-end project deliveries.
- It has 95 tasks drawn from 20 scenarios in 18 sectors, adapted by experts from real projects. Agents work in simulated environments with scripted counterparts and modifiable systems.
- Each delivery is scored by how much it improves the success metric of the client who hires the agent: 0 is leaving the system as it was and 1 is matching the reference solution. Messages, trials and waiting times are penalized.
- 13 model configurations from seven providers were evaluated.
Why it matters
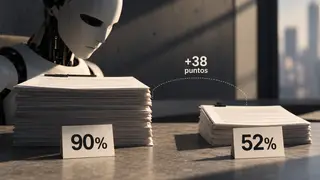
- In the realistic scenario, where the constraints have to be discovered, the leading configuration reaches a mean score of 0.56 and solves 14 of 95 tasks, that is, it reaches 0.8 or more with no incidents. Discovering the unsaid is the bottleneck; without explicit guidance, performance drops sharply.
- Getting the data is not enough. In the 23 tasks where the leading configuration gathered all the key facts, only 10 reached 0.8 or more. In other words, having the information doesn’t guarantee using it well either.
- For a Chilean small business that hires a “ready to use” agent, the work of surfacing implicit rules (what gets invoiced differently in a certain month, what exception the operations manager accepts) remains human. Whoever leaves it out of the contract finds out later, when the agent is already in production.
The number
14 of 95: the tasks solved by the leading configuration, with a score of 0.8 or more and no incidents.
Context
The name alludes to forward-deployed engineers, who set up inside a company to adapt a system to its processes. Other benchmarks already show the gap between executing and finishing: agents that declare themselves done before they are and email agents that fail despite executing well.
What’s next
- In the abstract, the authors do not announce new versions of the benchmark.
- No timelines announced.
Bottom line
The scenarios are simulated and the counterparts scripted: the result sets a floor, not the error rate of a real project. That distance is the next pending measurement.
Sources
- FDE-Gym: The Last Mile of AI Delivery, arXiv 2610.22350, October 15, 2026. We read the published abstract, not the full text.
Edited by Rodrigo Cornejo. How we select and verify: who writes these notes.