What happened
- A study announced on September 29 evaluates whether open-weight models generate synthetic respondents that preserve human statistical structure, and not just plausible answers.
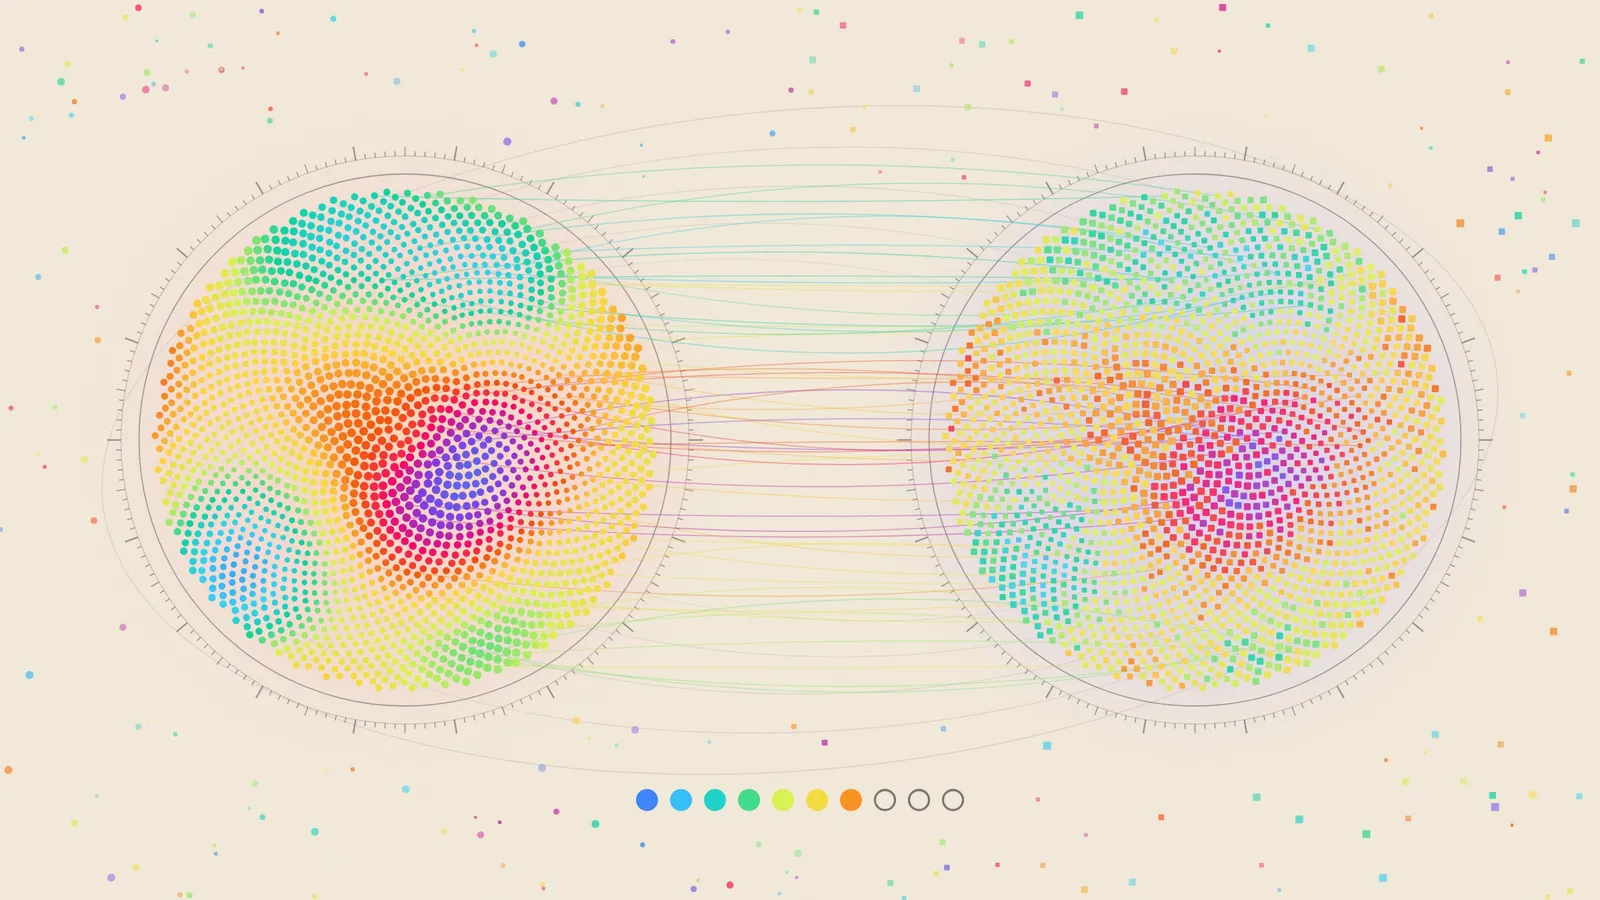
- The method conditions each simulated person on the verbatim answers of a real respondent to one psychometric instrument, and then measures it with a second, different instrument, controlling for the distance between constructs. The comparison point is a human panel of 2,058 people.
- Across a grid of 139 pairs, the simulated cross-correlation tracks the real human one with r between 0.70 and 0.73 in the three families tested. The result rests mostly on getting the sign right and concentrates in pairs at medium distance.
- The uncomfortable finding: capability does not improve steadily between versions. In a paired panel, the newest of three Llama versions tested performs worse on two of the three main metrics.
Why it matters
- Reproducing the sign is not reproducing the magnitude. It is useful for ordering hypotheses before going into the field; it is not useful for replacing the sample or for reporting a percentage.
- The warning about versions is the operational part: updating the model can make the study worse with nothing in the process flagging it. The authors ask for version-specific verification that accounts for the distance between constructs, not a validation done once.
- For teams in Chile doing research with expensive samples, the reasonable use is narrow and worth saying so: prioritize what to ask, not publish how much each group answered.
The number
r between 0.70 and 0.73 across the three open-model families evaluated.
Context
We had already written about an audience simulator that anticipates up to 90% of the criticism of a launch. This paper contributes the reverse: it measures how much of the human structure is actually preserved, with a real comparison panel and models anyone can download.
What’s next
- No announced date for releasing the 139-pair grid or the calibration protocol.
- No timeline to extend the study to closed models.
Bottom line
Forbes Chile’s artificial intelligence study claimed that 34 is double 30. A synthetic sample with an r of 0.70 and a real sample badly read fail in different ways, but they end up on the same presentation slide. The difference is made by whoever reports the margin.
Sources
- Can Open-Weight Large Language Models (LLMs) Simulate Human Survey Populations? A Cross-Instrument Calibration Study, arXiv, announced September 29, 2026.
Written by Mamífero. Edited by Rodrigo Cornejo. See how we select and verify each note.