What happened
- A team from the University of Virginia, the US National Library of Medicine at the National Institutes of Health, the University of Illinois and the Dana-Farber Cancer Institute published a study in Nature Communications on October 28, 2026 on how to train search agents.
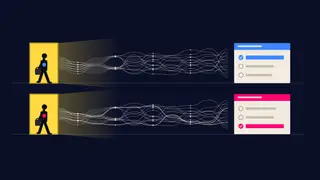
- The authors present RAG-Gym, a framework that moves supervision from the final answer to the search process itself: what query the agent issues, what it reads and how it decides the next step.
- With that framework they studied three fronts: the agent’s architecture design, the optimization of its parameters and the evaluation of each action.
- The result is Re2Search++, a process-supervised agent that, according to the paper, improves substantially on multi-step information-seeking benchmarks, especially outside the domain it was trained on.
Why it matters
- Language models are changing web search: instead of ranking documents, they synthesize answers, and increasingly they work as agents that query outside sources again and again.
- The usual method rewards the agent only when it gets the final answer right. The authors argue this leads to reward hacking and excessive reliance on what the model already memorized, which limits performance on new topics.
- The central finding is practical: the gains come mainly from better search queries, not from polishing the answer. An agent that asks better finds better sources.
- The search critics the system learned transferred to other models, including proprietary ones. That would allow the same critic to improve agents from different vendors.
The number
3 design fronts. RAG-Gym examines agent architecture, parameter optimization and action evaluation separately, and in that analysis identifies reflection on reasoning as a decisive capability.
Context
Retrieval-augmented generation, known as RAG, pairs a language model with a search engine that hands it documents before it answers. Search agents take the idea further: they decide for themselves how many times to search, what to ask and when to stop.
The problem the study tackles is that good intermediate steps are hard to generate and to evaluate. If only the outcome is checked, an agent can be right by chance, or from memory, and learn bad search habits that fail as soon as the topic changes. Process supervision tries to correct that by evaluating each query and each decision.
The involvement of the National Library of Medicine and a cancer center suggests an interest in biomedical search, where a right answer for the wrong reasons can be a risk.
What’s next
- The abstract does not report the computing cost of supervising every step, a figure that will decide its use in products.
- The transfer of critics to proprietary models opens the door for small teams to improve agents without retraining the base model.
Bottom line
Agent training is moving toward rewarding the path, not just the goal: ThinkingBox rewards the agent for the database it leaves behind and GRAFT lets a model cheat and then erases those shortcuts. On how research agents behave, see what an agent does when the user has already left and how deleting old reasoning cuts tokens by 25.5%.
Sources
- Nature Communications — Supervising the search process produces reliable and generalizable information-seeking agents (Xiong et al., October 28, 2026; date confirmed in Crossref)
- Cover image: TBurmeister (WMF), CC BY-SA 4.0, via Wikimedia Commons
Edited by Rodrigo Cornejo. How we select and verify: who writes these notes.