What happened
- A team published SRE-Marathon on September 29, a benchmark for site reliability agents that drops the one-fault-per-run format.
- The agent is invoked at fixed intervals with the accumulated alert history and a workspace that persists, while it operates a real two-zone Kubernetes deployment and an orchestrator injects overlapping faults on a schedule calibrated with production data.
- Faults arrive as they do in reality: through noisy alerts, stacked in time and often originating in code or configuration changes. The curated changes are deployed through the same build chain that is available for repairs.
- Each run is recorded in a sealed bundle and scored afterward. Across three applications and about sixty faults per run, the top-scoring method out of ten reaches 41.3 out of 100.
Why it matters
- The finding is not the score but its shape: agents correlate and locate the fault, but almost never complete the repair while the fault is still active. They are useful for shortening the diagnosis, not for closing the incident.
- That defines exactly what can be delegated today in a small team: the overnight shift gains by getting to the right place sooner, not by resolving things without anyone waking up.
- For a company in Chile running with teams of two or three people, the difference is one of budget. An agent that diagnoses doesn’t replace the shift; it makes it shorter.
The number
4AI assistants failed on the same day without any of them confirming a common cause. A benchmark that measures overlapping incidents instead of an isolated one looks a lot more like that day than like the tests these systems are sold with.https://www.mamiferolab.com/notas/caida-simultanea-asistentes-ia
What’s next
- No announced date for releasing the fault orchestrator or the sealed run bundles.
- No timeline to extend the benchmark beyond the three applications evaluated.
Bottom line
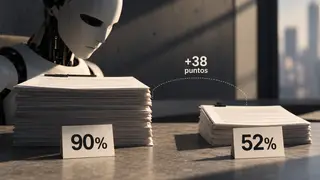
We already knew that agents declare themselves done 38 points more often than the evaluator approves. A system that says it repaired something while the fault is still active is not a measurement error: it is the same gap, now with a downed service on the other side.
Sources
- SRE-Marathon: A Continuous, Change-Driven Benchmark for Autonomous Site Reliability Agents, arXiv, announced September 29, 2026.
Written by Mamífero. Edited by Rodrigo Cornejo. See how we select and verify each note.