What happened
- A paper posted to arXiv on September 24 presents ExplorationBench, a set of tests to measure whether an AI system explores or merely remembers. It is signed by a team of twenty authors led by Ming Zhang.
- The design solves two measurement problems at once: how to verify a new hypothesis and how to tell discovery apart from recall.
- The solution is verifiable “alien worlds.” The rules are executable, so every answer can be checked exactly, and they contradict familiar knowledge, so memory isn’t enough to solve them.
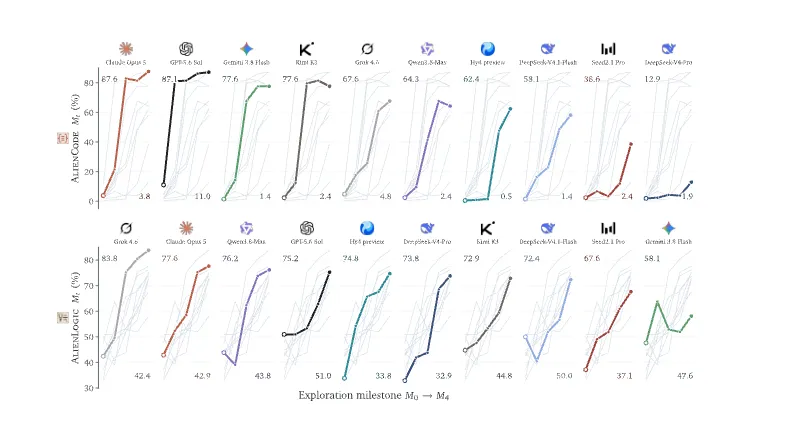
- There are two environments: AlienCode, with 31 discovery goals and 70 tasks, and AlienLogic, with 24 goals and 70 tasks. Each provides manuals with deliberate errors, feedback from the environment and tool schemas.
- Across ten systems evaluated, the best ones acquire and apply unknown rules, but performance fluctuates sharply between trajectories and some get worse the more they explore.
Why it matters
- The instability between attempts is the finding with practical consequences. If a system solves a task and fails the same task on another attempt, any promise of autonomy in a business process needs a retry-and-verify mechanism that nobody is budgeting for today.
- Manuals with deliberate errors mimic real working conditions in any organization: outdated documentation and rules nobody wrote down. A benchmark that punishes trusting the manual measures something clean evaluations don’t see.
- Systems that get worse as they explore more contradict the assumption that more steps and iterations improve the result. Anyone sizing an inference budget per task should look at that figure before scaling.
The number
140 tasks spread across two environments with 55 discovery goals.
Context
Agent evaluations keep running into the same problem: test sets end up leaking into training data and accuracy rises without capability changing. This year’s response was to build executable, verifiable environments instead of lists of questions. This adds a twist: the rules are designed to contradict what was learned.
What’s next
- The paper has been available on arXiv since September 24. No timelines announced for releasing the environments or a public leaderboard.
Bottom line
Measuring exploration requires a world where nobody has been before, and building that world is harder than building the model that travels it. That’s why almost every evaluation still rewards memory.
Sources
- “ExplorationBench: Measuring AI Systems’ Exploration in Verifiable Alien Worlds”, arXiv 2609.30199
- Our previous coverage: the test of aesthetic judgment in agents, models that don’t recognize their own code and the Navier-Stokes case without understanding of the problem.
Edited by Rodrigo Cornejo. How we select and verify: who writes these notes.